Ver categorias
Português
$
USD
Conecte-se à sua IA
Senior Data Engineer specializing in Cloud ETL and Architecture
Still relying on slow SQL Server refreshes?
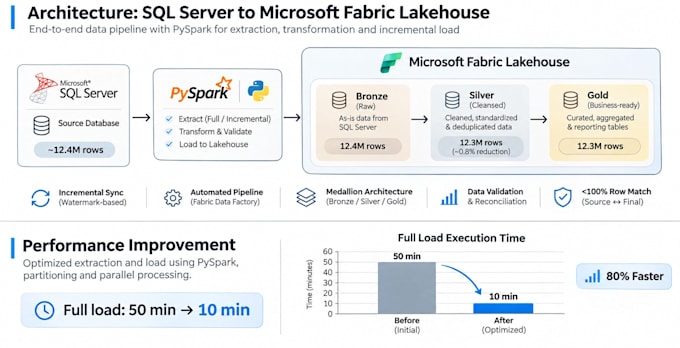
Ill migrate your SQL Server tables to Microsoft Fabric Delta Lake, building optimized full-load and watermark-based incremental pipelines.
What I deliver:
My hands-on experience: Built Fabric pipelines with staged upserts and incremental loading, reducing execution time from ~50 to ~10 minutes through optimization.
Ideal for teams modernizing legacy SQL Server and SSIS workflows.
Share your schema and row counts to get started. Message me before ordering for large migrations.
Warehouse Platform:
Azure Synapse
•
Fabric Warehouse
•
Databricks
Tipo de projeto:
Migração
Do you work with on-premise SQL Server or Azure SQL?
Both. For on-premise, share a schema export and sample rows. For Azure SQL, I can connect directly. Mention your version (SQL Server 2016, 2019, 2022, or Azure SQL) when messaging me.
Do I need a Microsoft Fabric workspace already?
No. The Premium package includes Lakehouse and workspace setup from scratch. For Basic and Standard, a Fabric trial or paid workspace is needed. I can guide you through setup as an add-on.
What is a watermark-based incremental pipeline?
After the initial full load, the pipeline uses a timestamp or auto-increment column to extract only new or changed rows from SQL Server and upsert them into Fabric Delta tables, no full reload needed. Your data stays continuously up to date.
Can you migrate stored procedures and views?
Table data and PySpark pipeline logic are included. Stored procedure conversion to Fabric notebooks or T-SQL equivalents can be added as a custom order message me with details first.
How do you handle tables with 100M+ rows
I design with partitioning, batch extraction, and incremental logic from the start. For very large tables, the Basic package's migration plan will include the recommended partition key and batch strategy before any code is written.
Do I get the code and can I maintain it myself?
Yes. All PySpark notebooks, pipeline logic, and documentation are yours. Standard and Premium include inline code comments and a step-by-step README so your team can extend or maintain the pipelines independently.